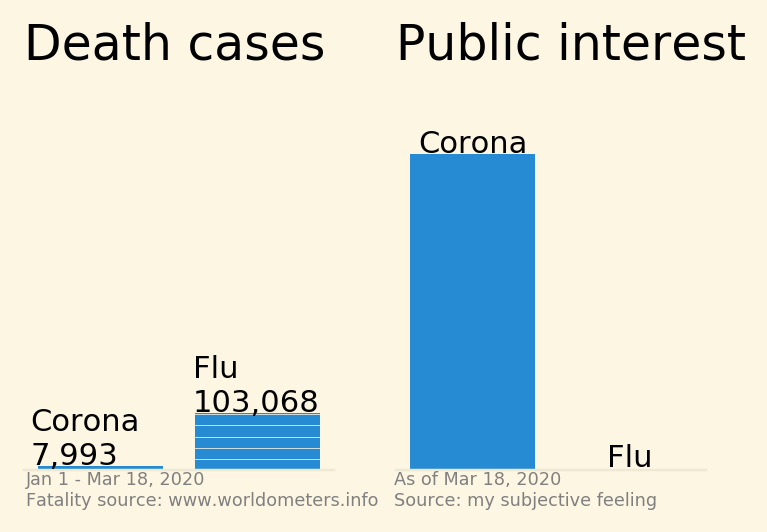
Graph code: here.
Graph code: here.
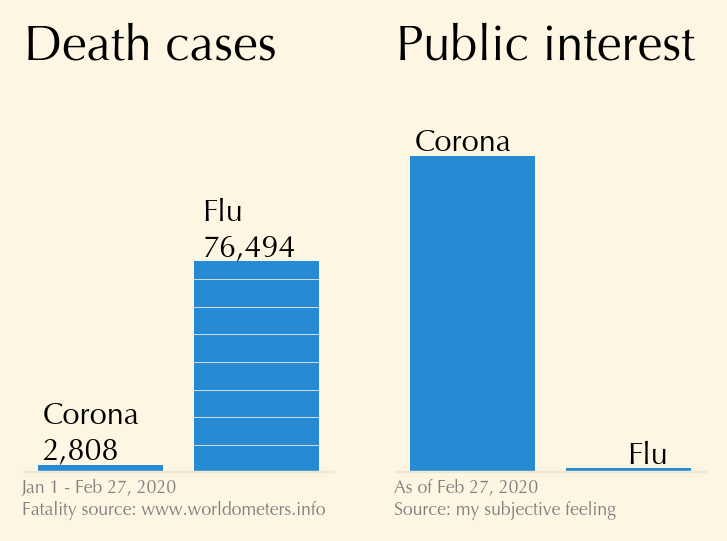
A data giraffe is a situation where a very prominent data point shades everything else. I learned this term from a post by Pini Yakuel and immediately liked it a lot.
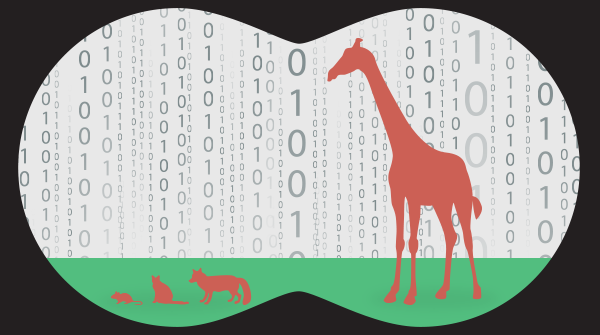 Taken from https://www.optimove.com/blog/beware-the-giraffes-in-your-data
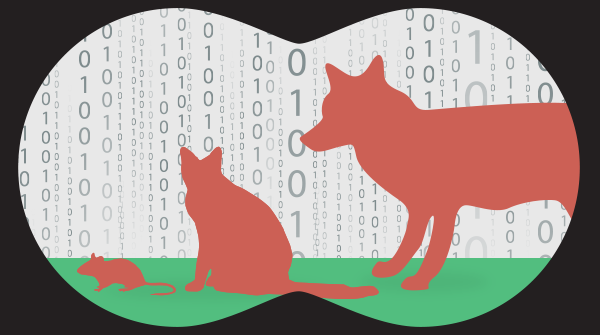 Taken from https://www.optimove.com/blog/beware-the-giraffes-in-your-data
Dealing with data giraffes is hard, especially when dealing with bar charts. Today I saw one interesting approach to this problem
Katherine S. Rowell is a co-funder of a Boston firm that specializes in data visualization. In December, she published apost dedicated to one of the most popular but also most abused graph types, the bar charts. One of the examples in her post demonstrates a nice treatment of data giraffes
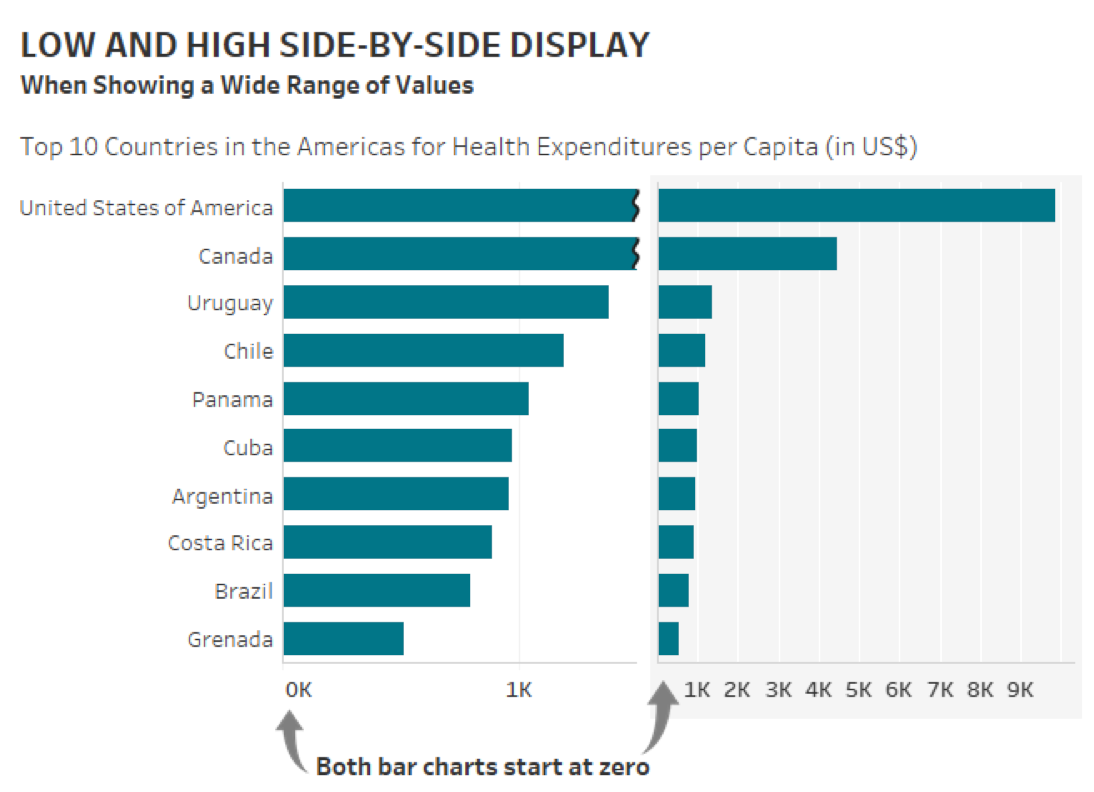 http://ksrowell.com/blog-visualizing-data/2019/12/18/bar-humbug/
In this example, Katherine draws the graph twice. The zoomed-out version shows the giraffes in all their glory, while the zoomed-in one gives the spotlight to the foxes, hyenas, and mice.
Also, note how these graphs respect the rules that every bar chart has to include the zero.
Here’s another email that I got with the question about switching to the data science career
Hello, my name is X. I saw your blog, and to be honest, I said, “Wow, is this me :)” I’m a pharmacist 5th-grade student currently working on a project in computational drug design. I started programming, and I loved it. After that, I heard the term “Data Science” and started to do some research […]
Basically, I loved being on a computer and solving problems its a good career option for me (at least for now, you can’t predict future) my mom has a pharmacy I worked there (internship), and it is not for me (i am counting the time when I’m in a pharmacy.) so I have a few questions for you
I don’t have any degree in statistics or CS or something equivalent I am determined to learn these topics, but some people want to see the degree, and probably no one accept a pharmacist to a master degree in statistics (I also wish to do my Ms in computational drug design because, in the end, I don’t want to be a data scientist in social sciences or economics, at least for now, I want to use that knowledge in my field which is drugs and pharmaceuticals)
Ph.D. on Bioinformatics would help ? or Biostatistics ( is it easier for us to be accepted in biostatistics rather than statistics? To be honest, I don’t know the difference much, I took a biostatistics class, but it was just one semester and probably not enough for Ph.D. :))
Do I really need a degree in CS or statistics to be a pharmaceutical data scientist? I want to do my Ph.D. but also want to be realistic, it sounds amazing doing online masters in statistics while you are doing Computational drug design or Bİoinformatics Ph.D., but it is very hard and frustrating and also decrease your productivity in both fields.
I asked a lot of questions, sorry, but I have many :). You can reply when you have time. Thank you, and I loved your blog. I read and watched tons of things, but yours was the best suited for me because being a pharmacist, computational drug design, considering bioinformatics, it is all fits. By the way, I also considering cybersecurity (not working in a company but learning). I see that as a “martial arts of the future,” maybe I am wrong, but a person should know it to protect him/her self. Thank you again :)
Indeed, X’s background sounds very much like mine.
I’m not sure I have too much to add to what I already wrote here, in this blog. The only thing that I have to say is that in my biased opinion, a Ph.D. is something worth pursuing. The more time passes by, the more Ph.Ds there are, and the lack of a degree might be a problem in the future job market. On the other hand, there are many smart and rich people who claim that university degrees are a waste of time. Go figure :-)
I hope that this helps.
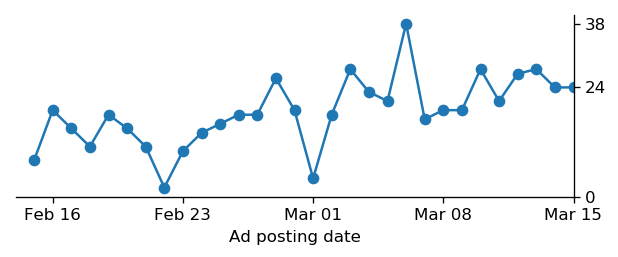
I suppose that you knot that THE software developement Q&A site has its own job board. I suspected that the Corona pandemic would lead to a sharp decrease in the number of job postings on that board. I scraped the data, and it looks like for now, there are no drastic changes in the amount of postings published in the last couple of days.
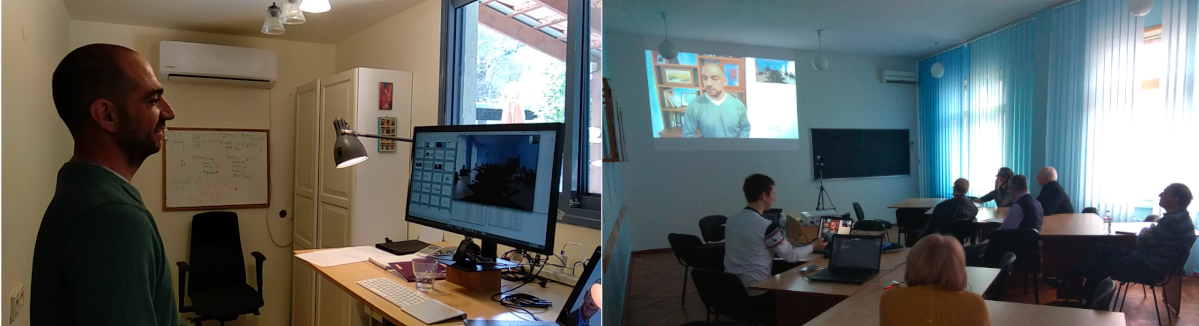
Before becoming a freelancer data scientist, I used to work in a distributed company. Remote communication, including remote presentations were the norm for me, long before the remote work experiment no one asked for. In this post, I share some tips for delivering better presentations remotely.
I am glad and proud to announce that a paper which I helped to prepare and publish is available on the Nature’s group site.
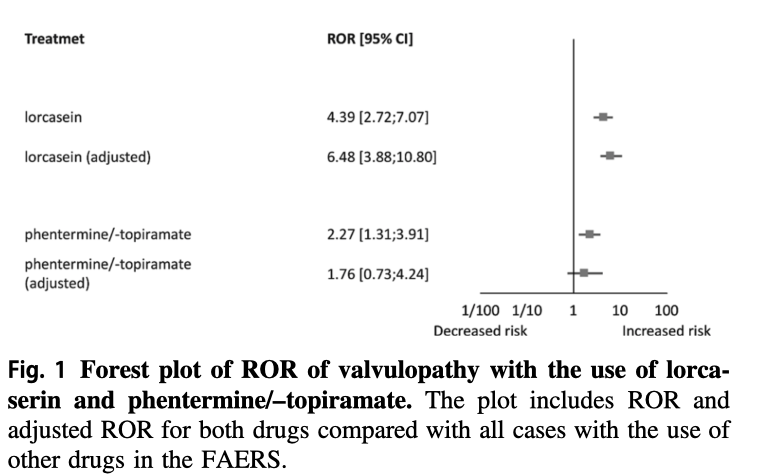
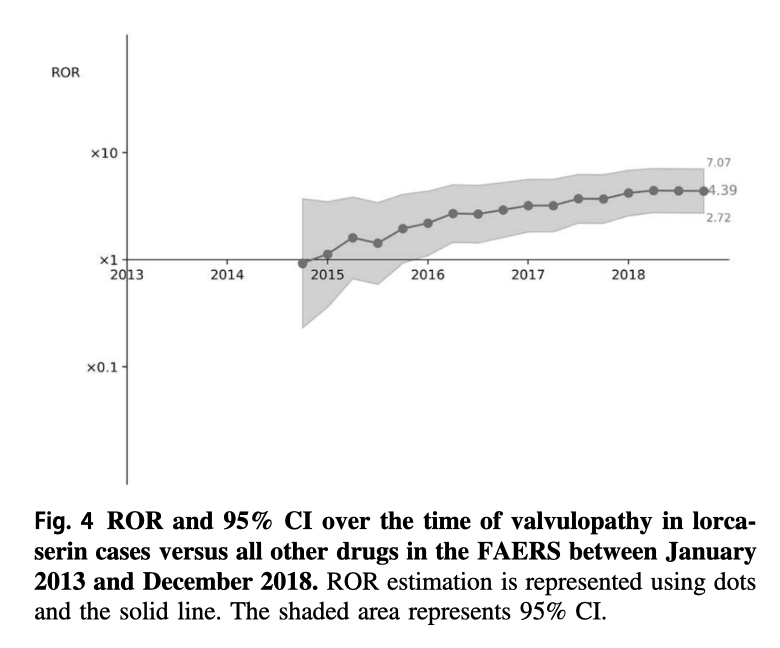
The paper, The cardiovascular safety of antiobesity drugs—analysis of signals in the FDA Adverse Event Report System Database, by Einat Gorelik et al. (including myself) analyzes the data in the FDA Adverse Event Reporting System (FAERS). In this study, we found interesting and relevant safety information about the long-term safety of the antiobesity drug Lorcaserin. Due to the interdisciplinary nature of the paper, the review process took about a year. Interestingly enough, the FDA requested the withdrawal of Lorcaserin due to long-term safety issues but not the ones we studied.

Please leave a comment to this post. It doesn’t matter what, it can be a simple Hi or an interesting link. It doesn’t matter when or where you see it. I want to see how many real people are actually reading this blog.
[caption id=”attachment_media-15” align=”alignnone” width=”1880”]
Photo by Pixabay on Pexels.com[/caption]
קראתי היום פוסט המדגים איך תרשימי עוגה יכולים להיות יותר יעילים מחלופות. מעניין שהפוסט משתמש פרלמנט הגרמני כמקרה דוגמה.
https://serialmentor.com/dataviz/visualizing-proportions.html
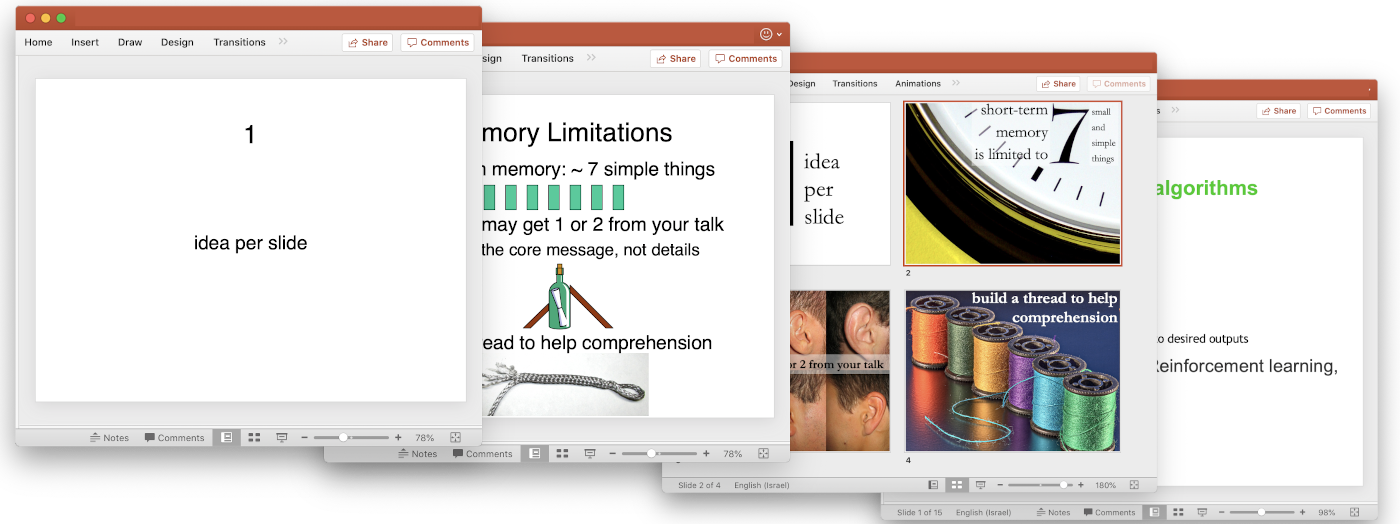
A lot of texts that talk about presentation design cite a very clear rule: each slide has to contain only one idea. Here’s a slide from a presentation deck that says just that.
And here’s the next slide in the same presentation
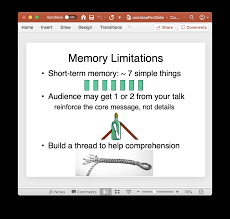
Can you count how many ideas there are on this slide? I see four of them.
First of all, we need to remember that most of the time, the slides accompany the presenters and not replace them. This means that you don’t have to put everything you say as a slide. In our case, you can simply show the first slide and give more details orally. On the other hand, let’s face it, the presenters often use slides to remined themselves of what they want to say.
So, if you need to expand your idea, split the sub-ideas into slides.
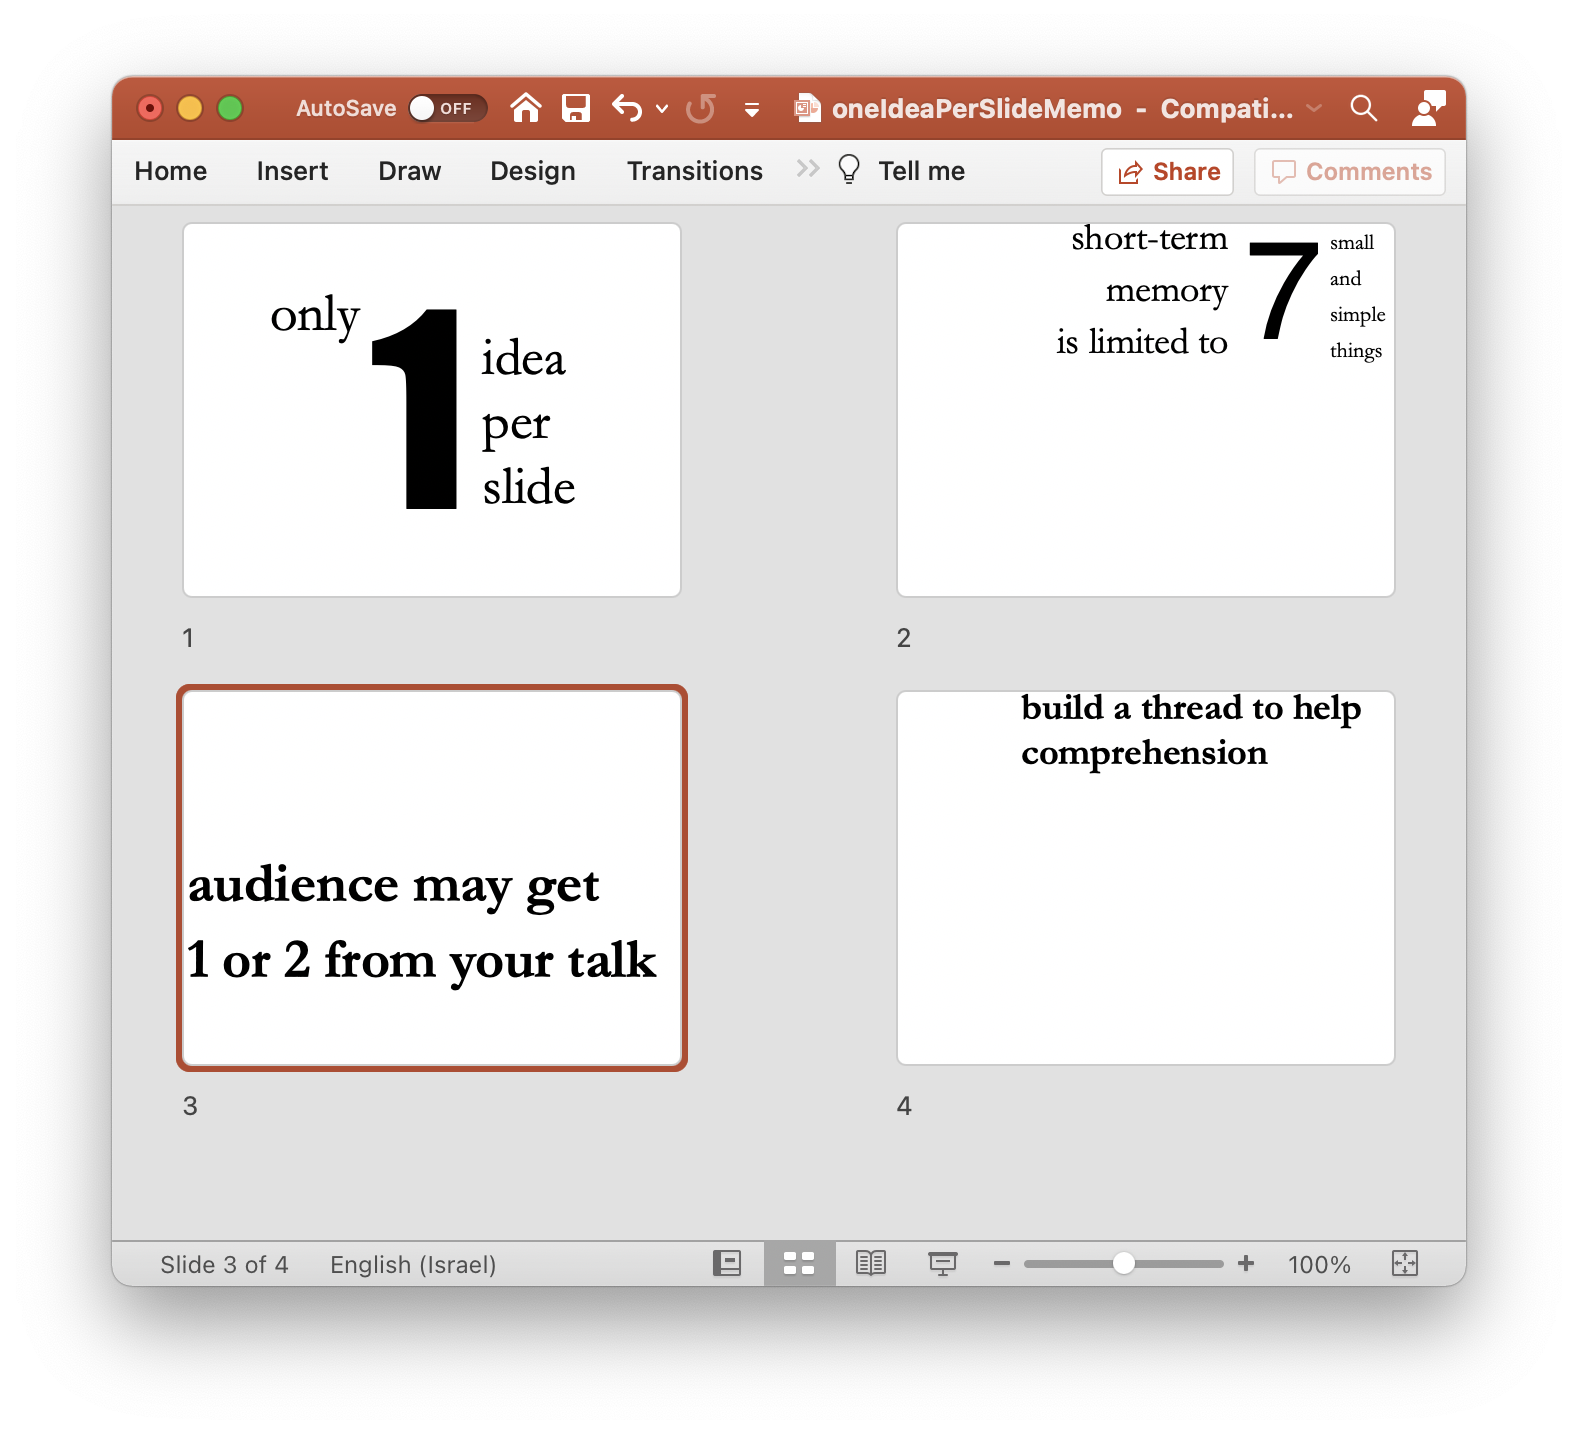
You can add some nice illustrations to connect the information and emotion.
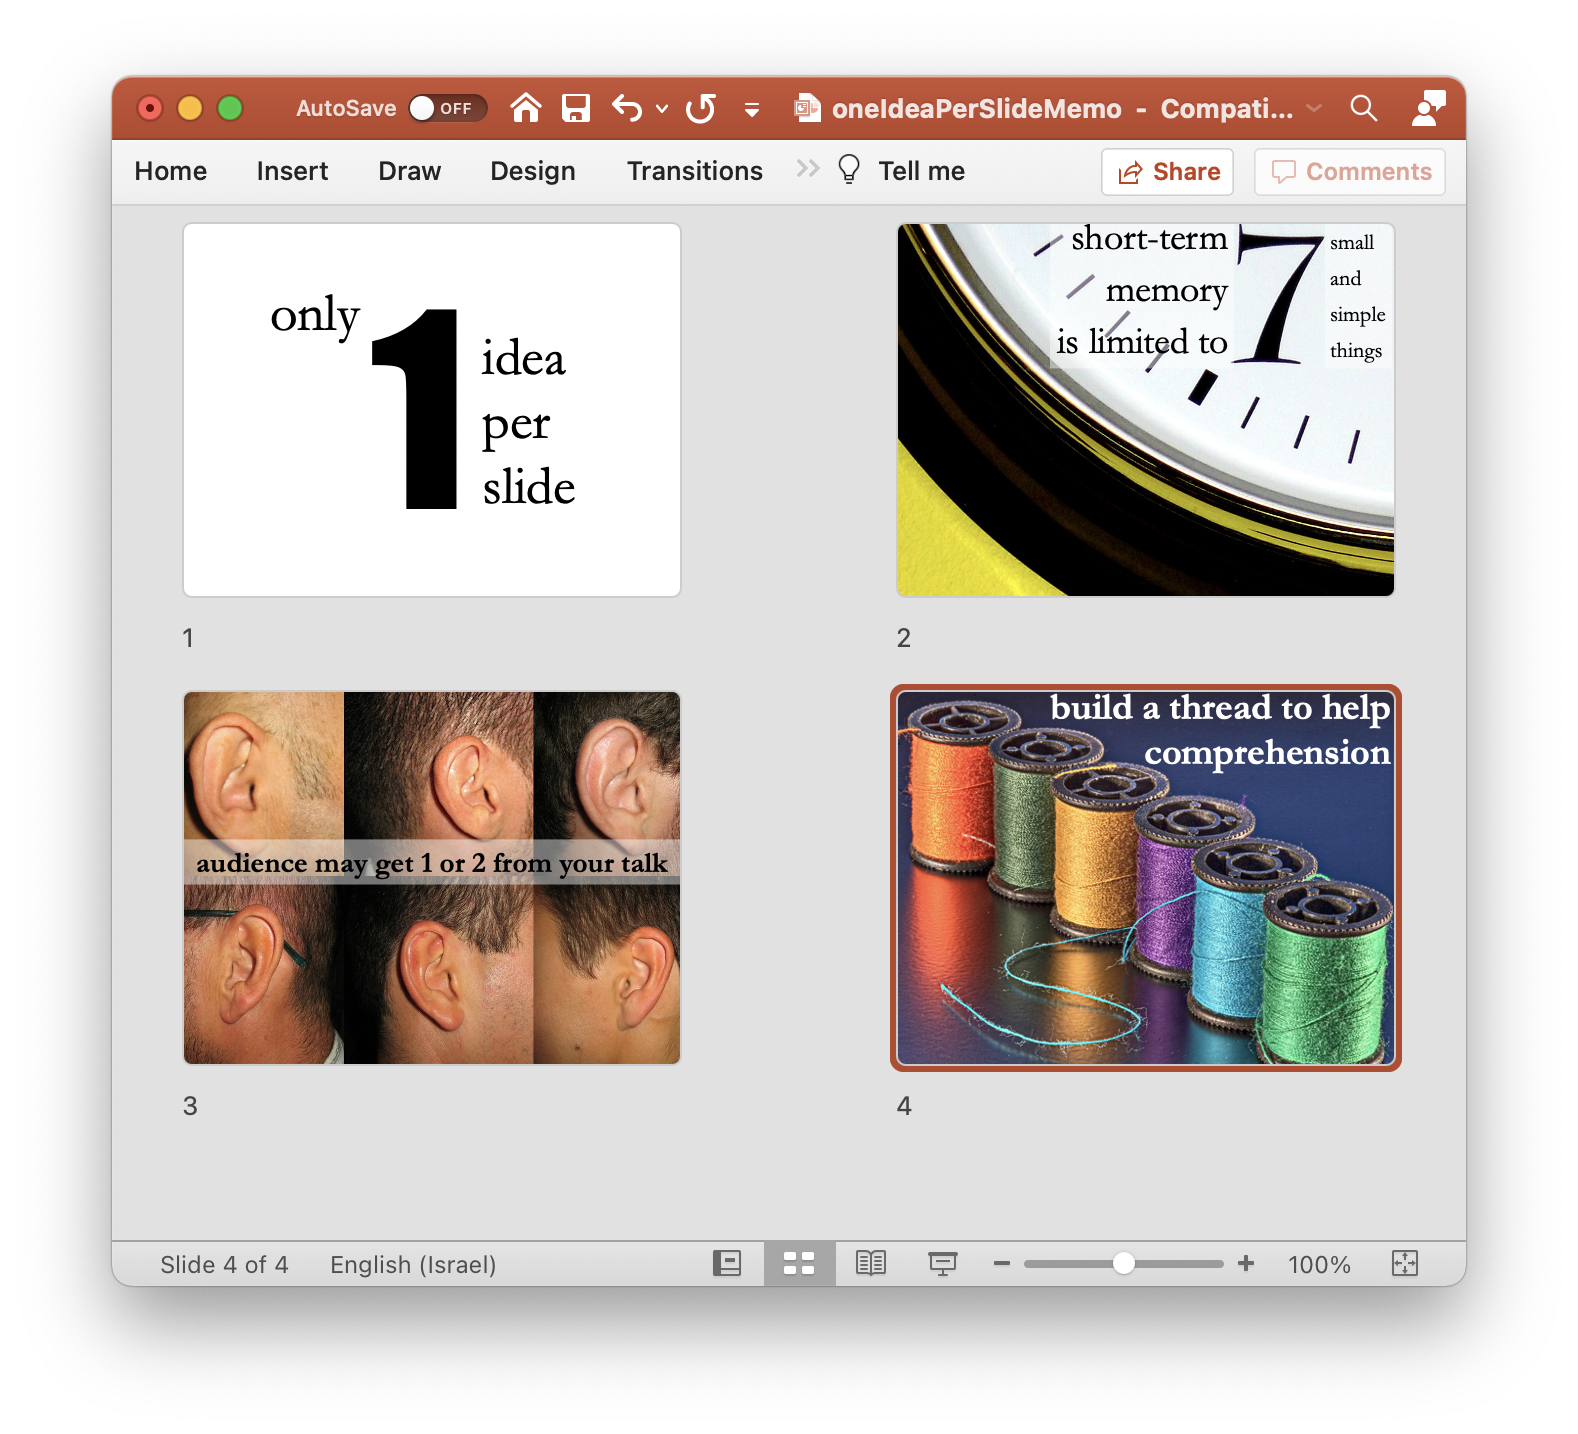
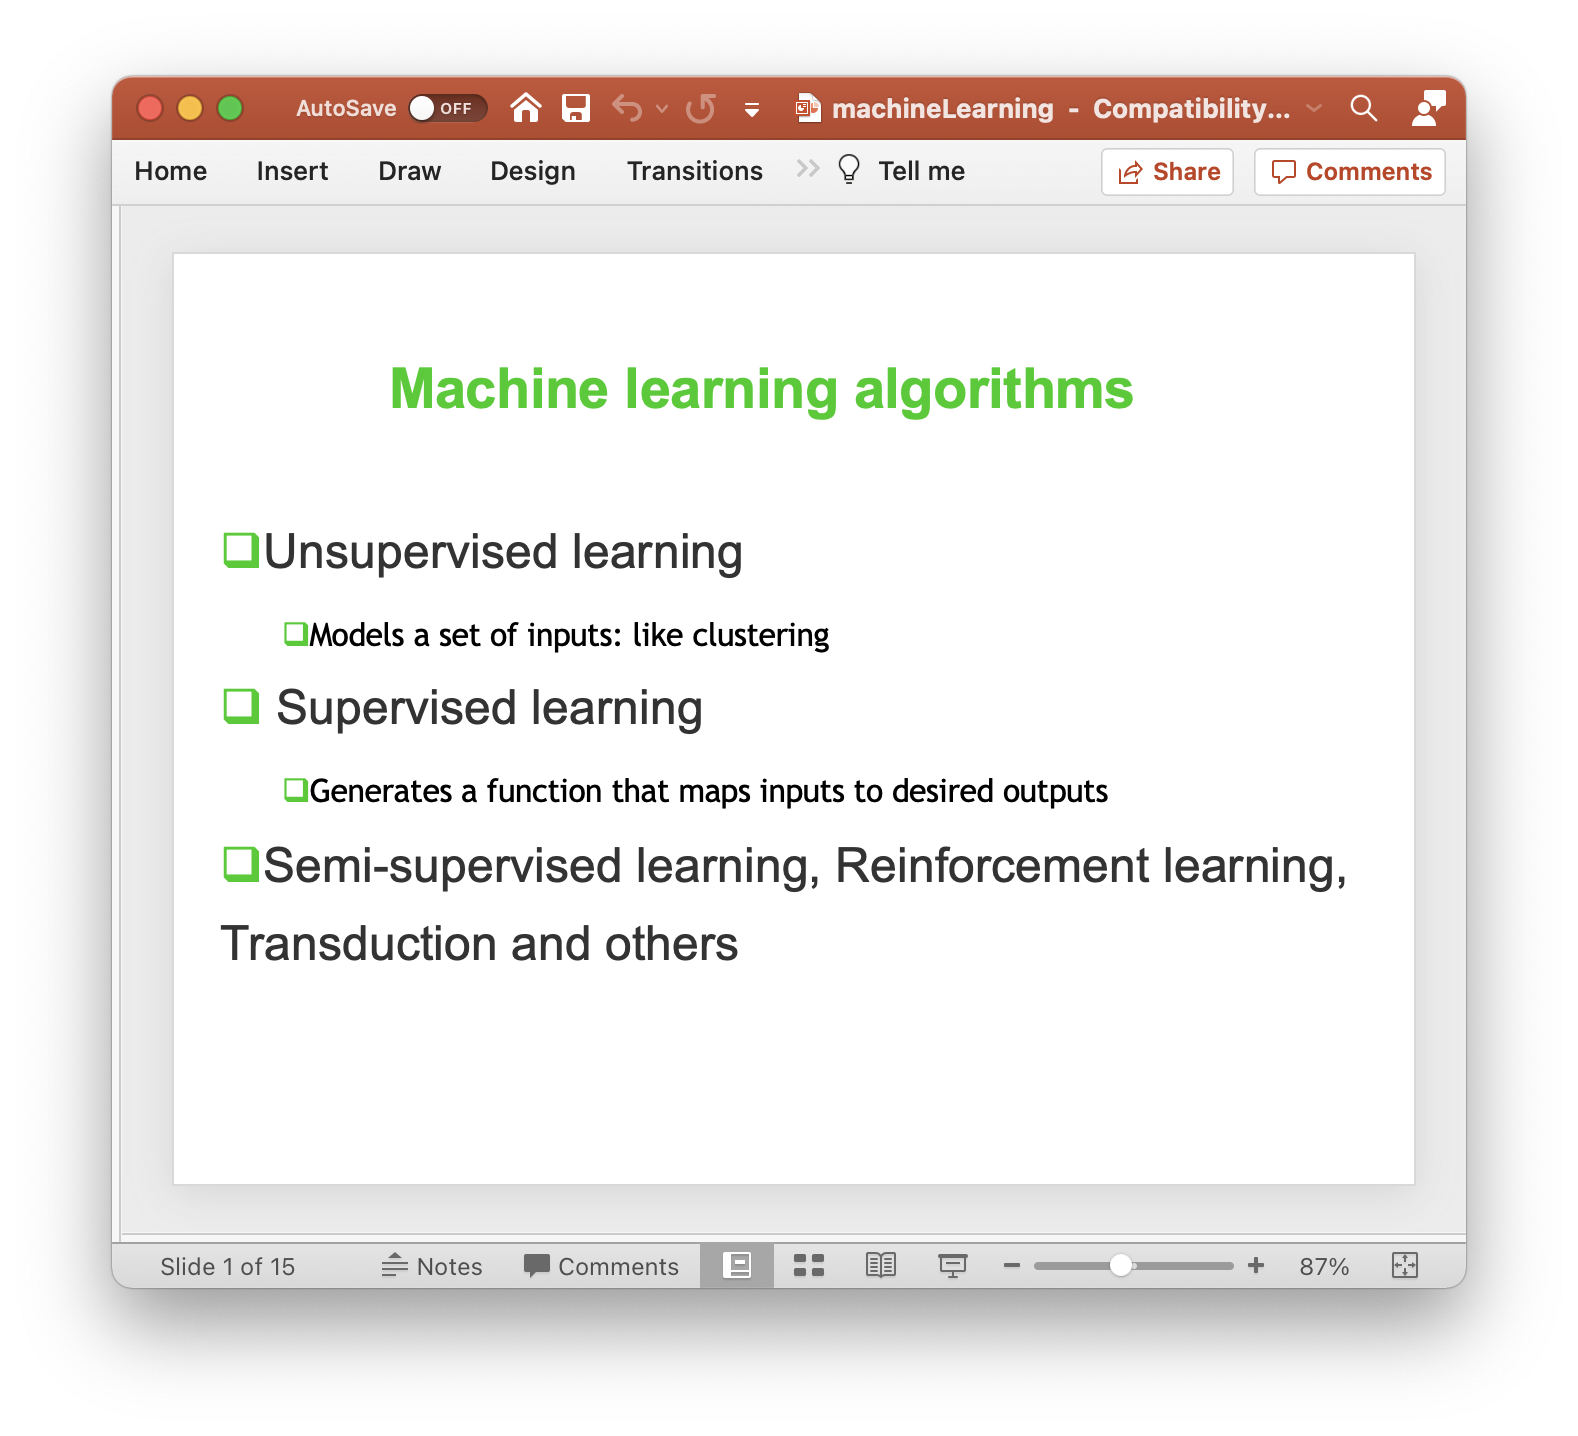
“Yo!”, I can hear you saying, “Motivational slides are one thing, and technical presentation is a completely different thing! Also,” you continue, “We have things to do, we don’t have time searching the net for cute pics”. I hear you. So let me try improving a fairly technical slide, a slide that presents different types of machine learning.
Does slide like this look familiar to you?
First of all, the easiest solution is to split the ideas into individual slides.
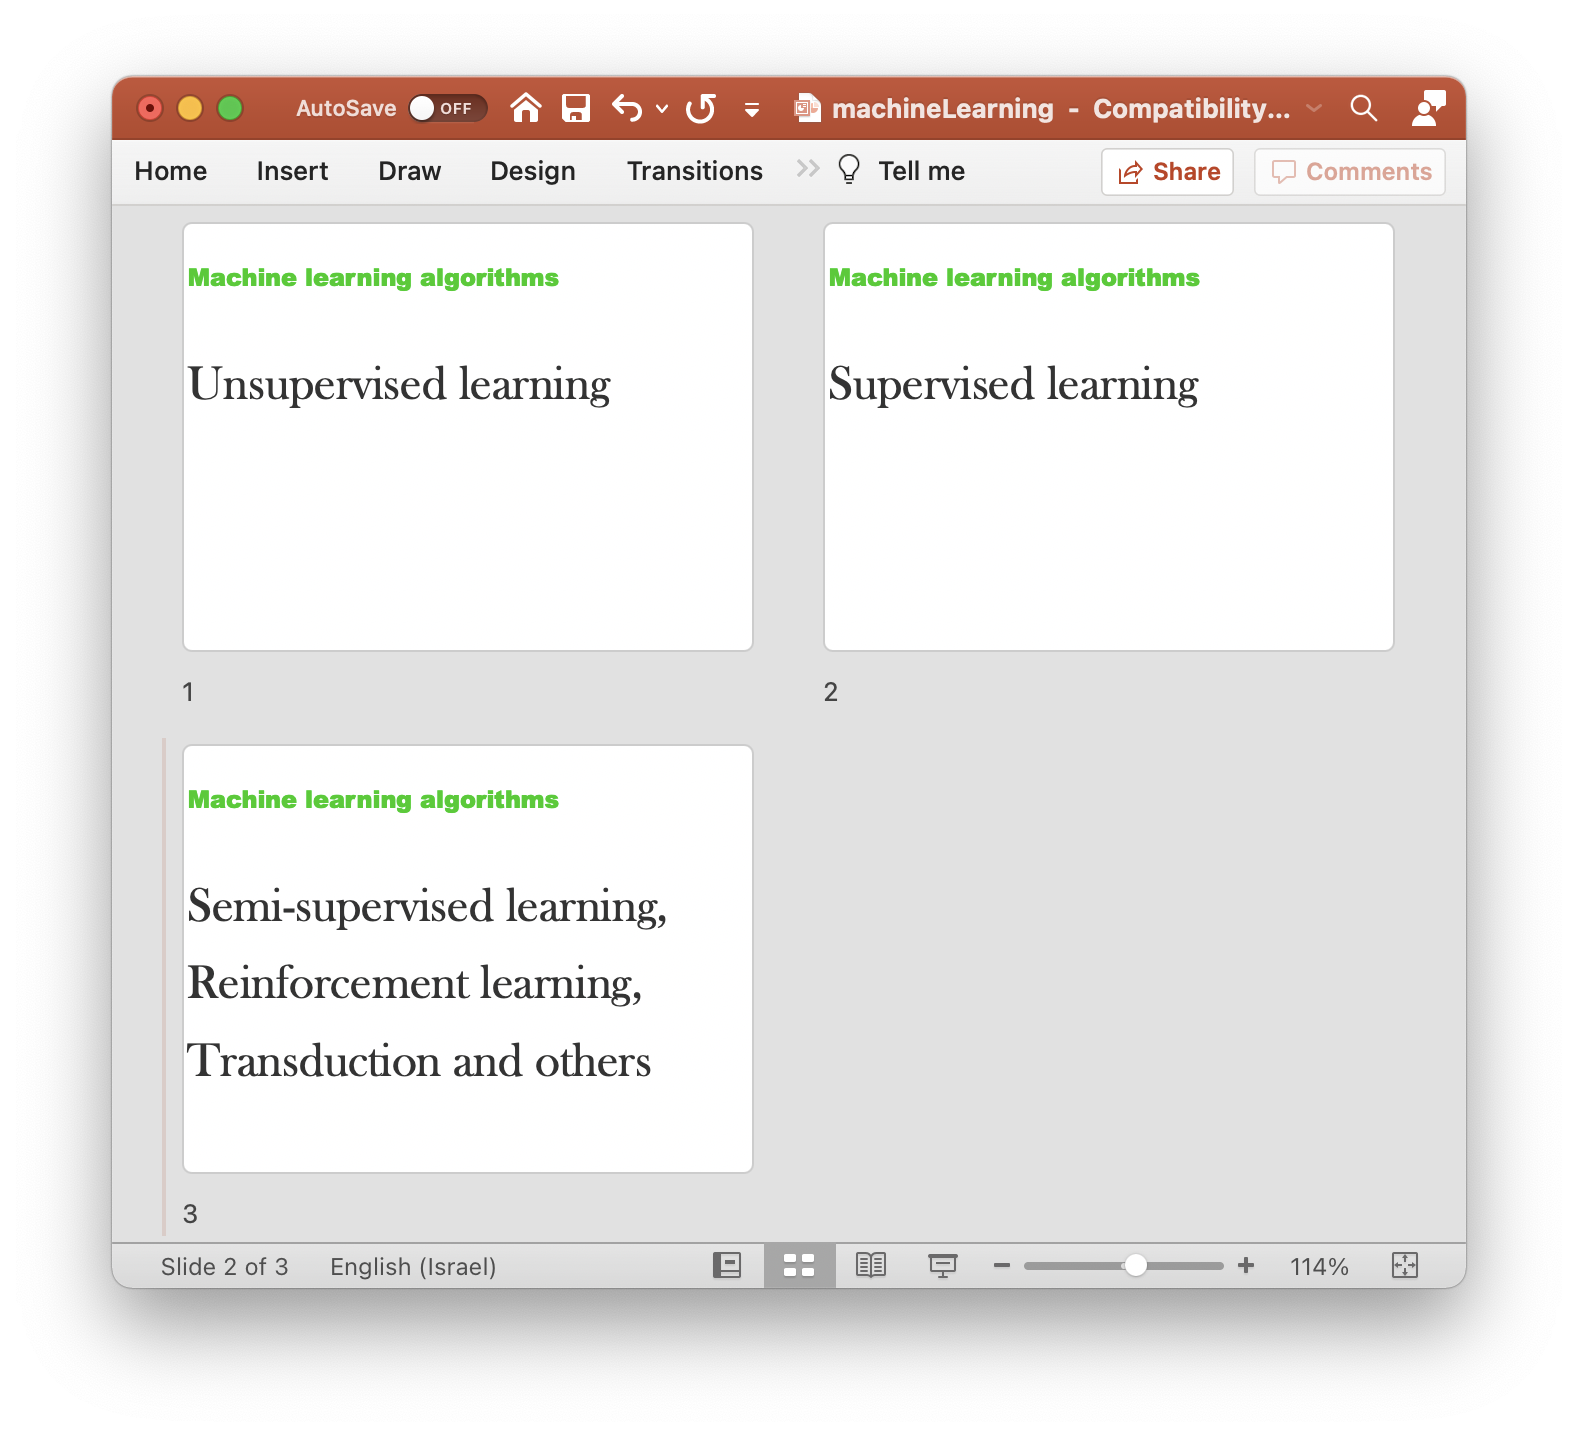
It was simple, wasn’t it. The result is so much more digestible! Plus, the frequent changes of slides help your audience stay awake.
Here’s another, more graphical attempt
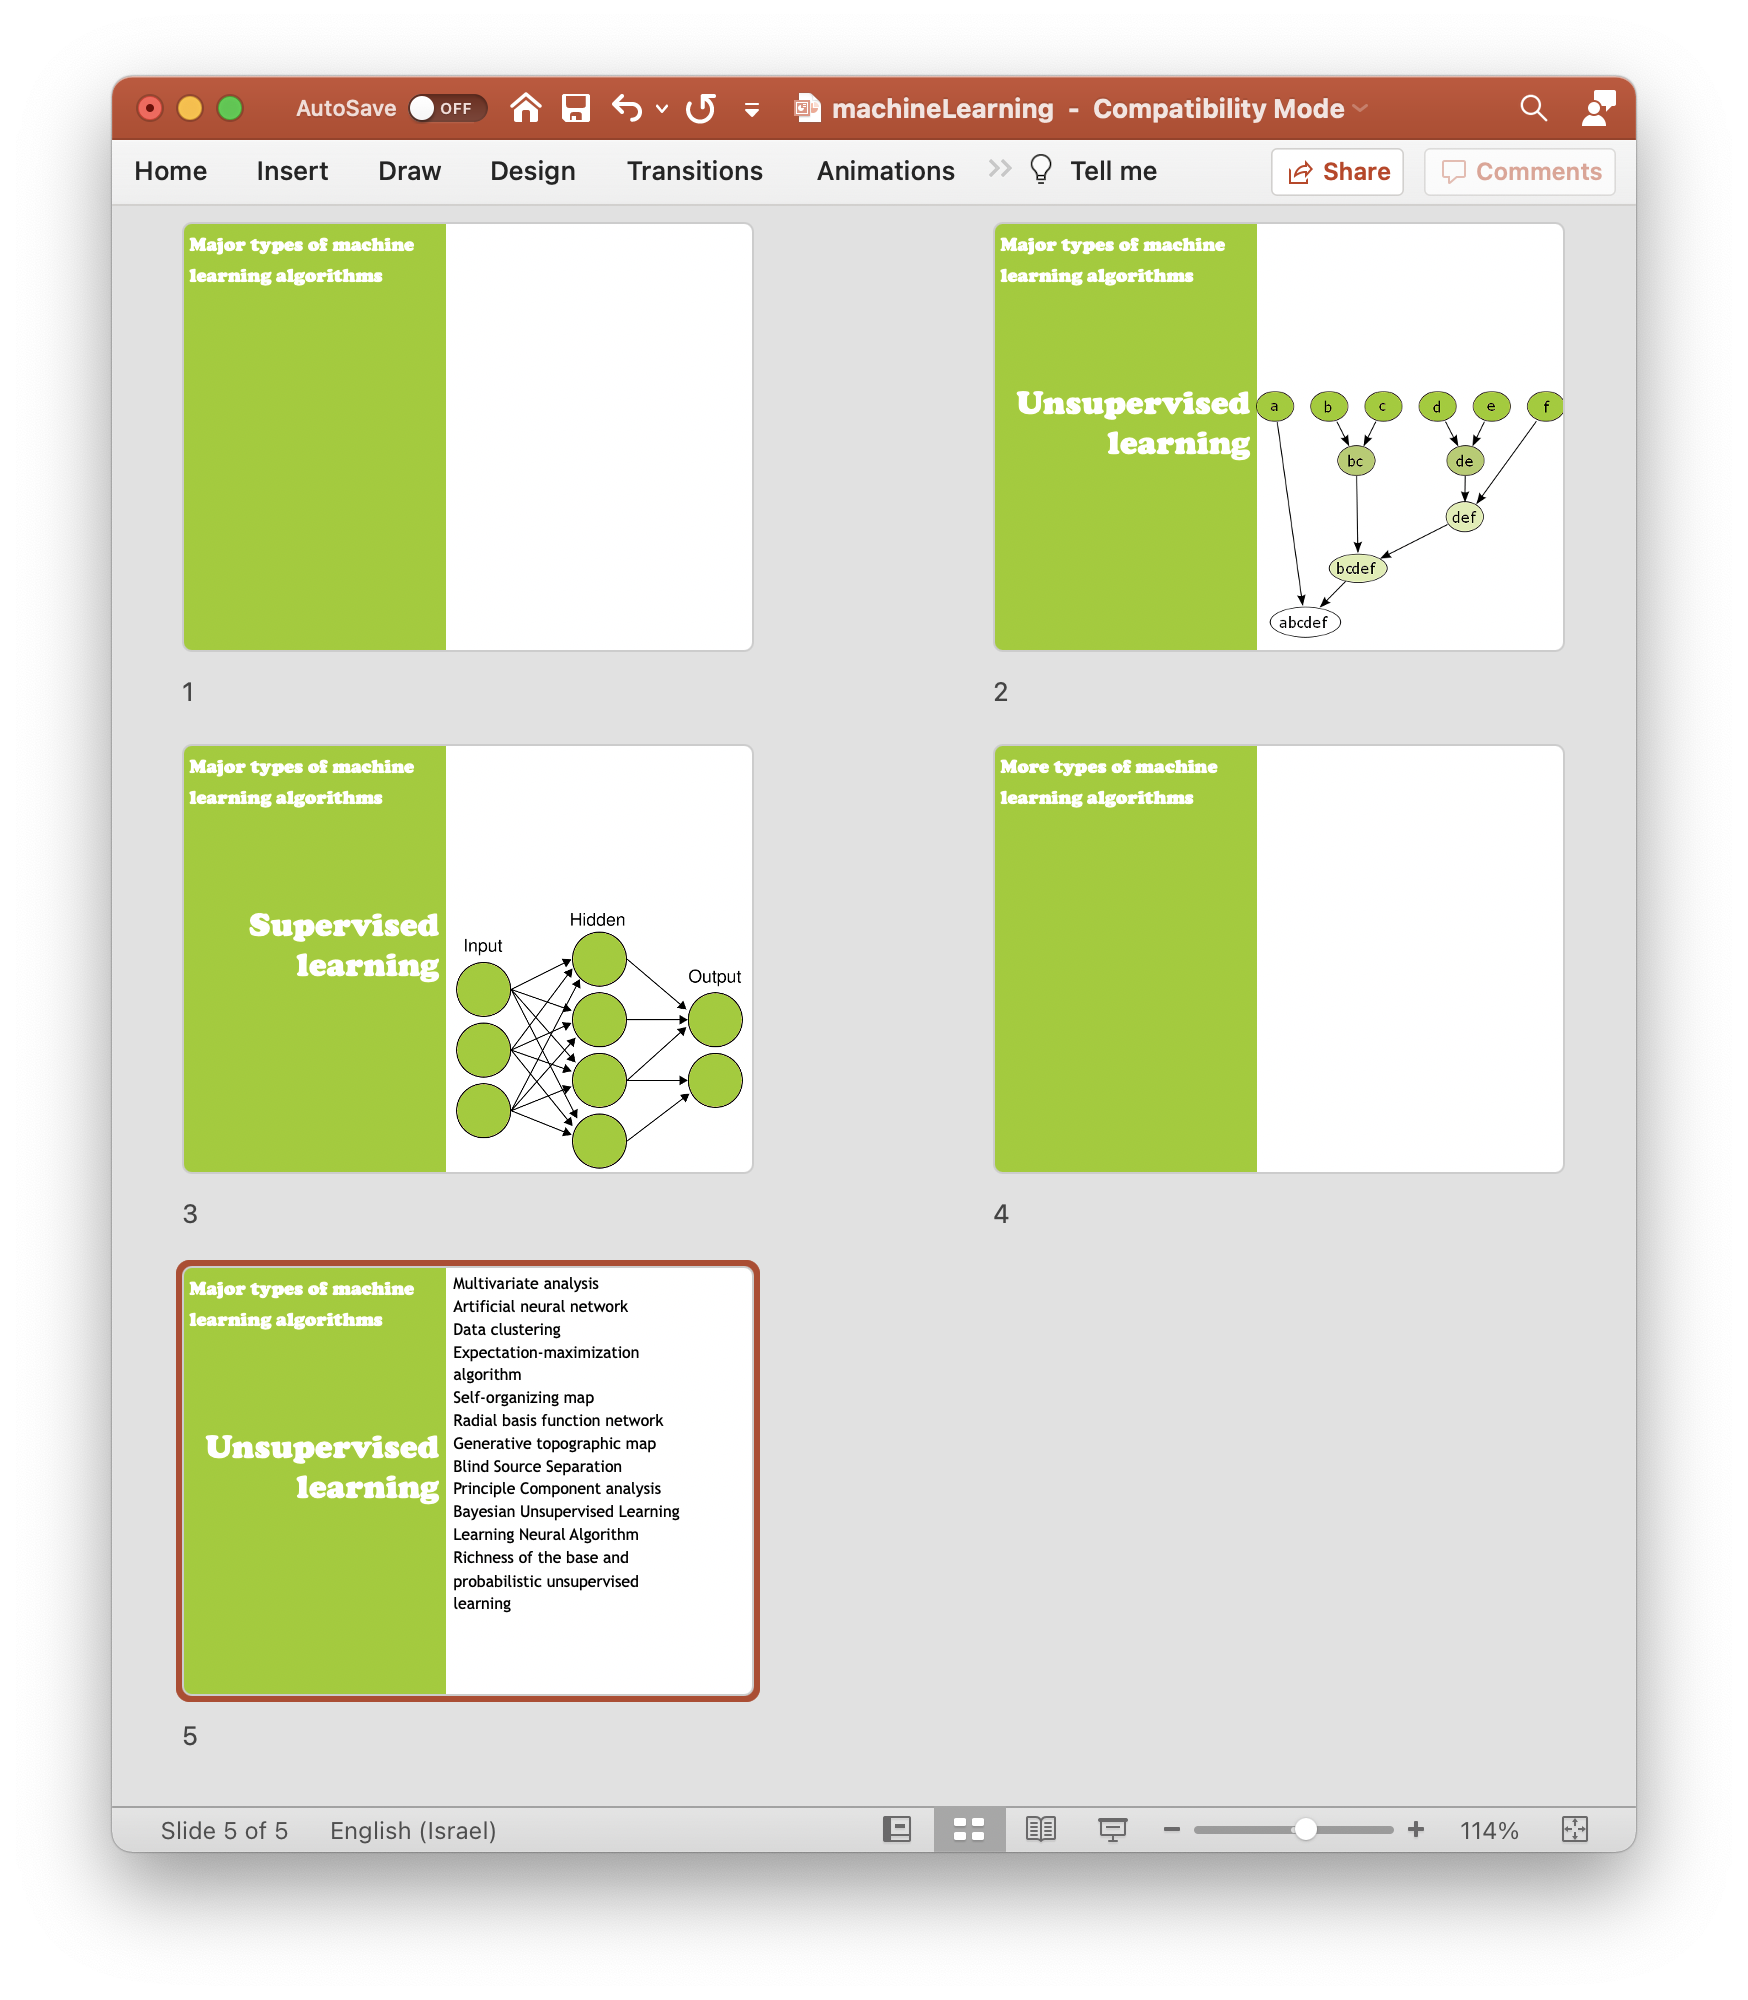
When I show the first slide in the deck above, I tell my audience that I am about to talk about different machine learning algorithms. Then, I switch to the next slide, talk about the first algorithm, then about the next one, and then mention the “others”. In this approach, each slide has only one idea. Notice also how the titles in these last slides are smaller than the contents. In these slides, they are used for navigation and are therefore less important. In the last slide, I got a bit crazy and added so much information that everybody understands that this information isn’t meant to be read but rather serves as an illustration. This is a risky approach, I admit, but it’s worth testing.
“One idea per slide” means one idea per slide. The simplest way to enforce this rule is to devote one slide per a sentence. Remember, adding slides is free, the audience attention is not.
Graph code: here.
People ask me for good intro video to data visualization. I tend to ask them to look for one of my lectures. To save the search, here’s one of the most relevant talks that I gave
Being a data science freelancer, and a long-time AnnMaria’s fan, I HAVE to repost here latest post on consulting success
Last week, I mentioned that successful consultants have five categories of skills; communication, testing, statistics, programming and generalist. COMMUNICATION Communication is the number one most important skill. All five are necessary to some extent, but a terrific communicator with mediocre statistical analysis skills will get more business than a stellar statistician that can’t communicate. Communication…
From time to time, I get emails from people who seek advice in their career paths. If I have time, I write them an extended reply and if they agree, I publish the questions and my replies here, in my blog. Here’s one such email exchange. All similar pieces of advice, as well as other rants about a career in data science, can be found here.
“Hi Boris :)
My name is XXXXX. I came across your blog while searching for people with a mix of pharmacy and data science skillsets. Your blog has been so informative to me so far but I was compelled to write to you to ask for your advice.
I am a clinical pharmacist by background but decided to leave the clinical pharmacy to pursue public health. Whilst doing my MPH, I fell in love with epidemiology and statistics and am now doing a Ph.D. in biostatistics. Your blog has made me feel very happy that I made this career move <…> I feel better about my decision to leave the pharmacy and pursue a quant Ph.D. I have gone from pharmacy, to internships at
In the past, I also felt that the pharmacy degree was confusing many potential employers, and since I wanted to leave the bio/pharma world and move to “pure data” positions, I omitted the B.Pharm title & studies from my CV. Ten years ago, the salaries in the bio sector, here in Israel, were much lower than the salaries in the “high tech” field. I think that today this situation is more or less normalized and that the people got used to the fact that a typical “data scientist” can have a very wide range of degrees.
“I was just wondering if I could get your opinion on the three questions I have. 1. I work part-time as a clinical pharmacist to not forget my clinical skills. What do you think about the future of the pharmacy career overall?”
 My last shift as a pharmacist
This is a huge question and I don’t have answers to it. Moreover, the answer depends heavily on legal regulations in the given country. I say that if you enjoy treating people, and can afford this time, why not? I, personally, was a very lousy pharmacist :-) so I was very happy to leave the pharmacy.
“I am wondering if I should keep up my pharmacist title or pursue data science full-time.”
Again, it depends. For many years, I didn’t have my pharmacy title in my CV because it felt unrelated to what I was doing. It was also a nice icebreaker to tell people with whom I worked “by the way, I’m a pharmacist” and it was fun to see their reactions. If I were you, I would ask two-three HR people or people who recruit employees what they think. Different countries may behave differently.
“2. At what point can someone call themselves a data scientist?”
In my opinion, as long as you are comfortable enough to call yourself a data scientist, you are good to go. Note that unlike many people who got their data science “title” after taking some online courses, you already have a very strong theoretical base. Not only are your Master’s and the future Ph.D. degree relevant to data science, but they also give you strong and unique advantages.
“I am looking at DS jobs at large tech companies. I am not sure how qualified and experienced I have to be for these jobs. I code in R using regression, clustering and time series methods and I am quite fluent in this language. I have just started to learn ML algorithms. I have a basic foundation in Python and SQL. I use Tableau for visualization and love communicating my research at any opportunity I get. I was wondering…how good do I have to be able to apply to DS jobs? What are the methods that data scientists use mostly? Would I be able to learn on the job?”
It sounds like a good combination of techniques. I am not recruiting but if I would, I would definitely like this list of skills. Personally, I don’t like R too much and prefer Python. But once you program one language, moving to another one is a doable task. As to what methods do data scientists use mostly, this hugely depends on your job. Most of my time, I clean data and write wrapper functions around known algorithms. The task that I have been facing during my professional life required regression, classification, network analysis. I never did real deep learning stuff, but I know people who only do deep learning for image and sound analysis. Also, in many cases, the data science part takes only 10% of your time because the “customer” doesn’t care about an algorithm, they want a solution. See this post for a nice example.
“3. If you had the opportunity to start your career again, say you were in your early twenties, what would you study and why? What advice would you have for your younger self? I would be so keen to hear what you think.”
It’s a philosophical task which I never like doing. What is done is done. The fact that I am a pretty successful data scientist may mean that I took the right decisions or that I was super lucky.
Being a freelancer data scientist, I get to talk to people about proposals that don’t materialize into projects. These conversations take time, but strangely enough, I enjoy them very much, I also find these conversations educating. How else could I have learned about a business model X, or what really happens behind the scenes of company Y?
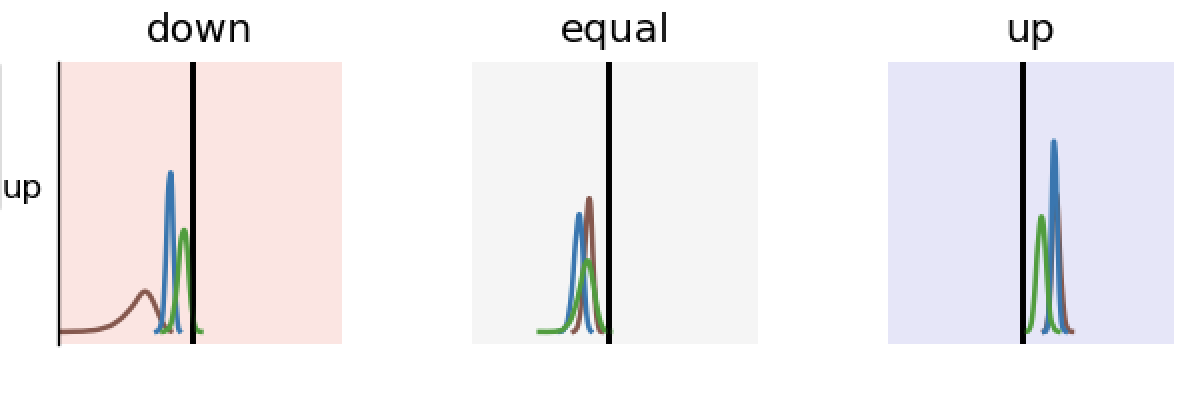
I can’t elaborate yet, but in case you wondered how scientific satisfaction looks like, here’s a perfect illustration.
Stay tuned
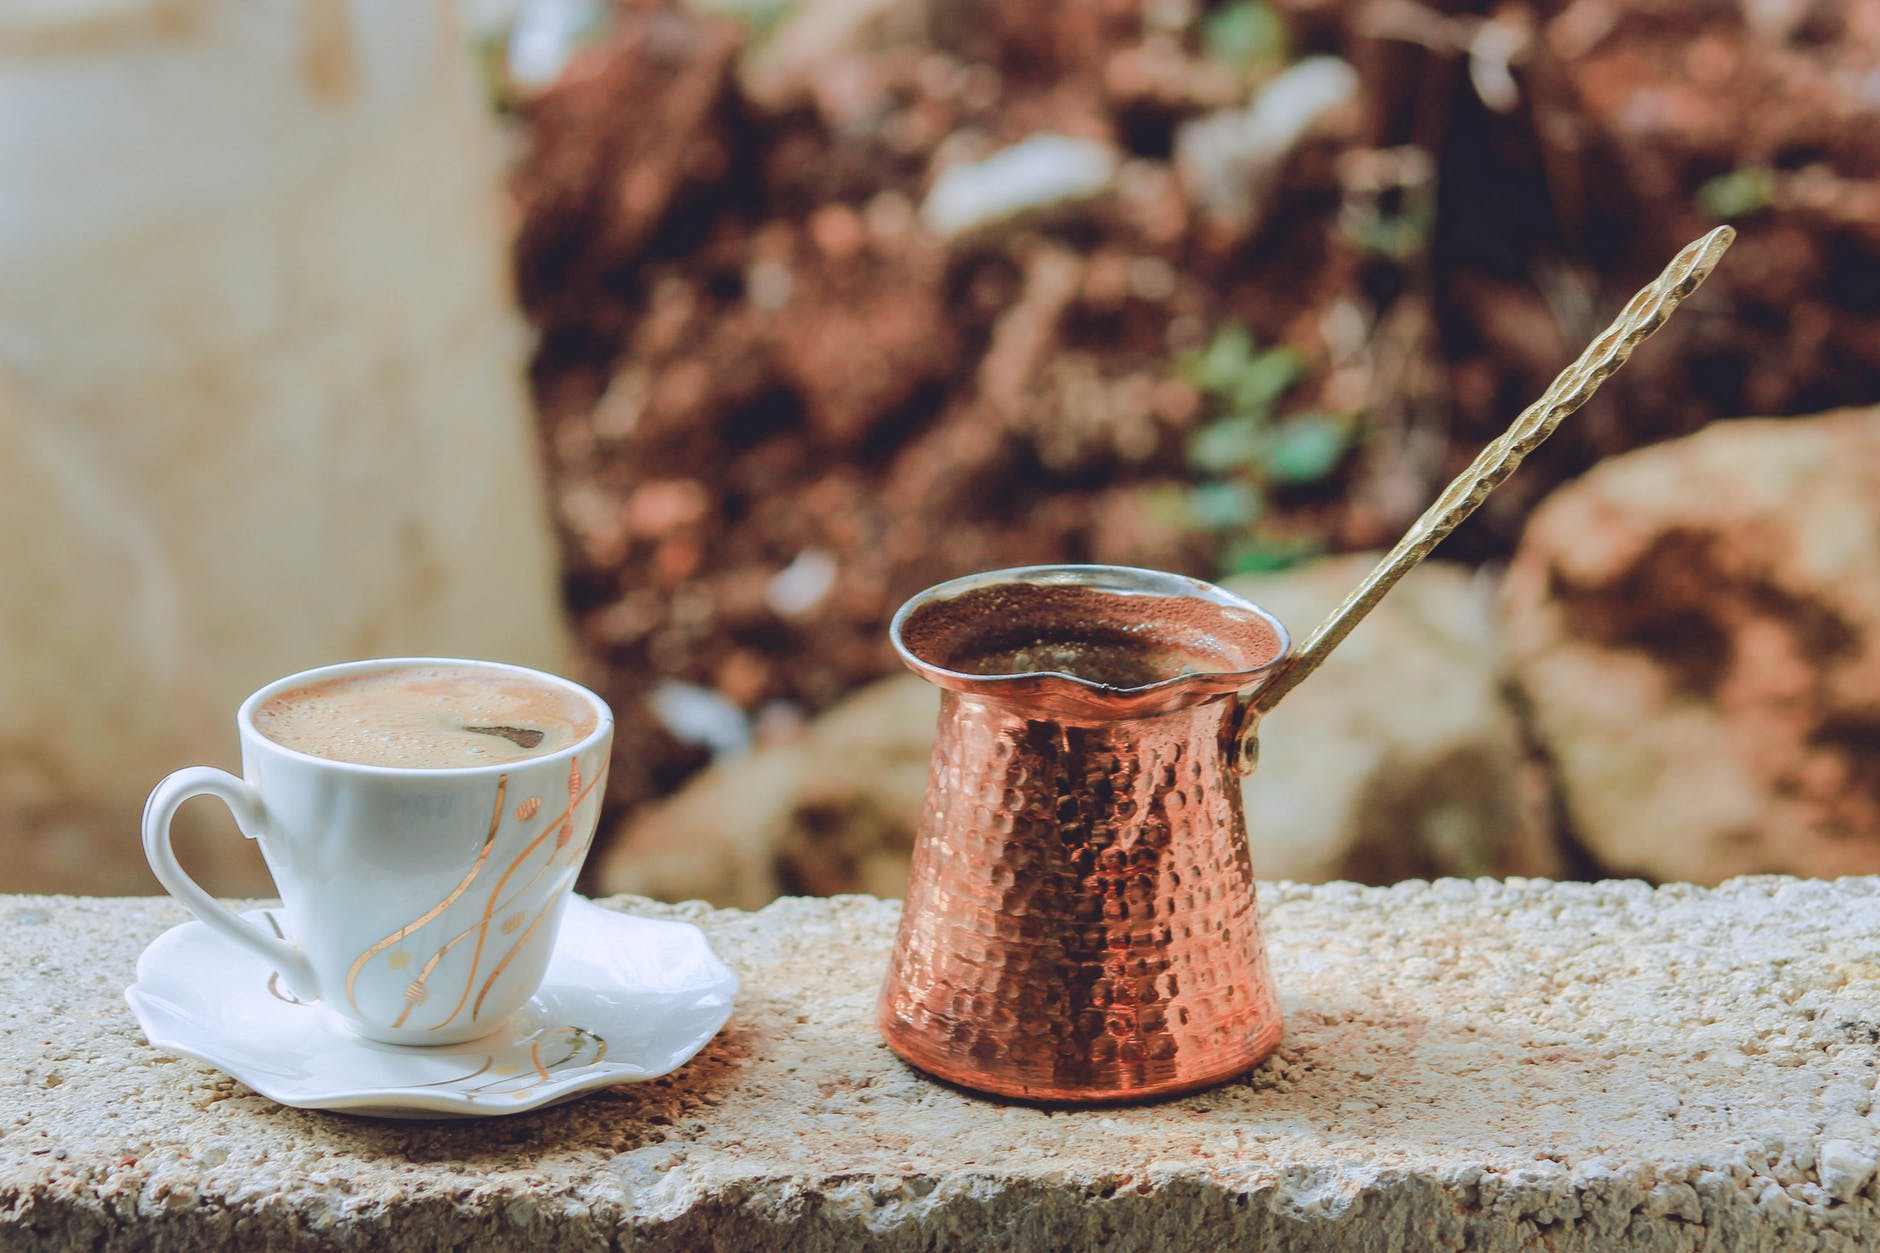
Gilad Almosnino is an internationalization expert. I’m reading his post “Eight emojis that will create a more inclusive experience for Middle Eastern markets,” in which he mentions “Turkish or Arabic Coffee,” which reminded me of my last visit to Athens. When, in one restaurant, I asked for a Turkish coffee, the waiter looked at me harshly and said: “It’s not Turkish coffee; it’s Greek coffee!”
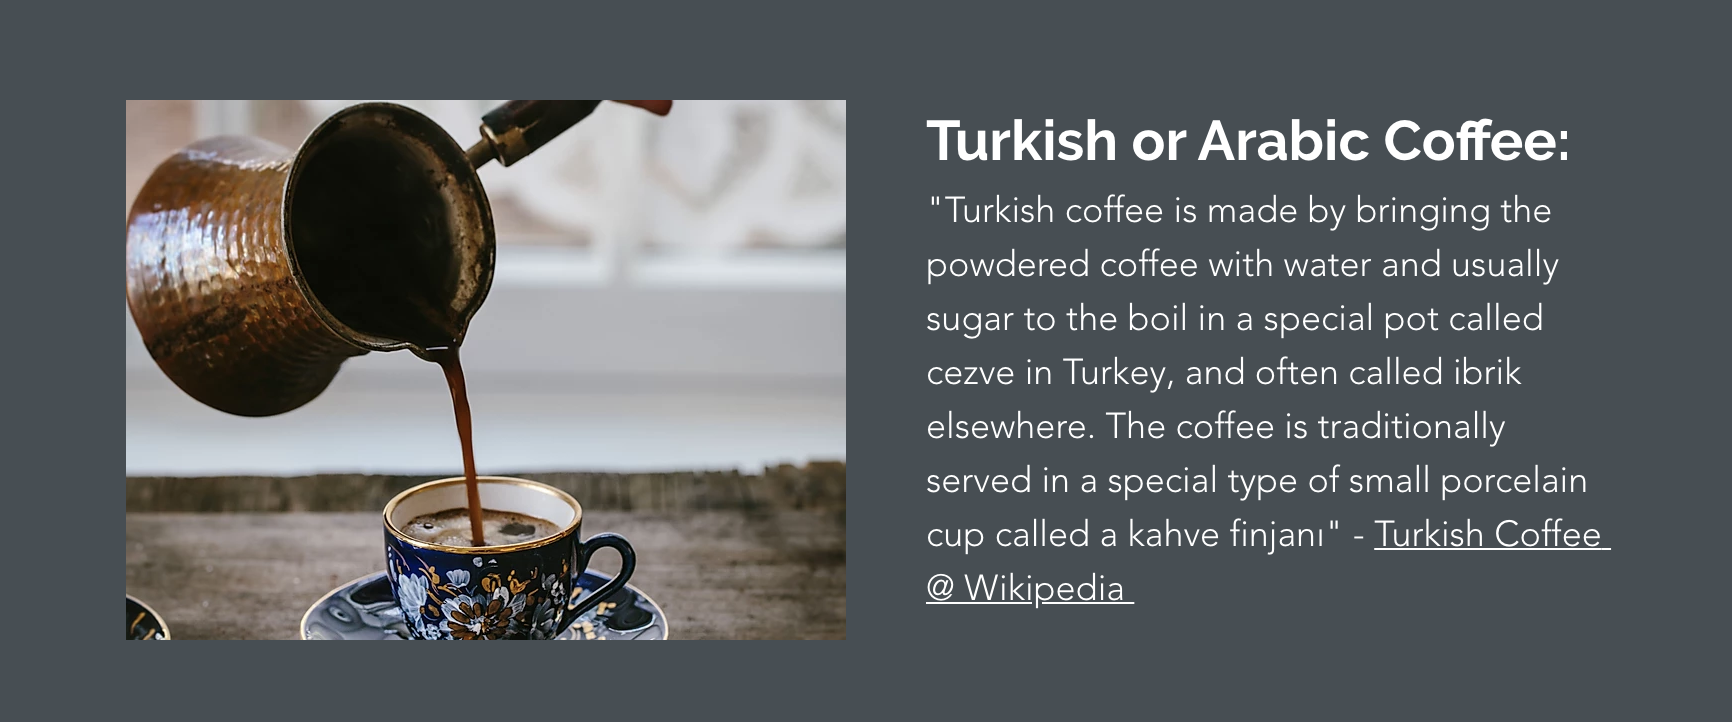
Turkish, Arabic, or Greek
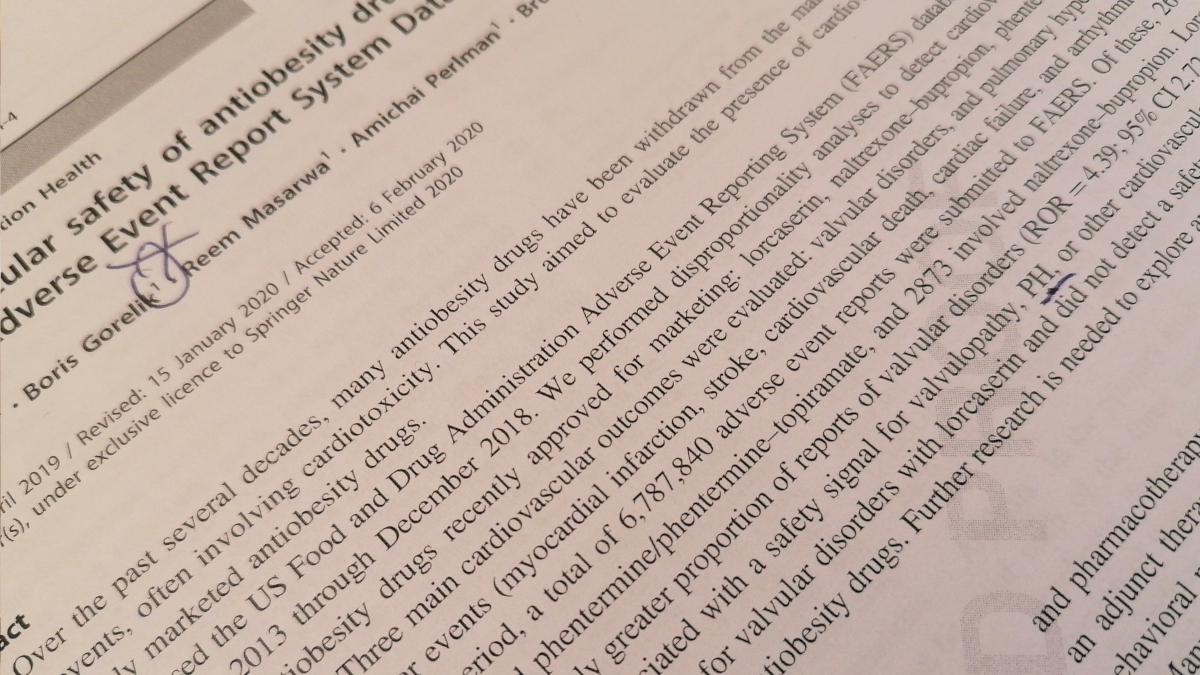
Do you believe in telepathy? Yesterday, I submitted final proofs of a paper in which I actively participated. During the proofreading, I noticed that our abstract ends with “further research is needed” and scratched my head. I submitted the proofs and then then, I saw this pearl in my blog feed
TL;DR shallow and disappointing
The Great Mental Models by Shane Parrish was highly praised by Automattic’s CEO Matt Mullenweg. Since I appreciate Matt’s opinion a lot, I decided to buy the book. I read it and was disappointed.
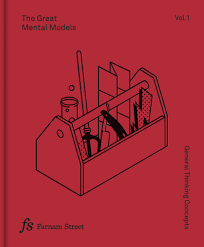
This book is very ambitious but yet shallow and non-engaging. If you consider reading a book on mental models, then chances are you already know some of them. I expected the book to shed light on aspects I didn’t know or didn’t think of. Nothing like that happened. I didn’t learn new facts, neither was I impressed by a new way of thinking. I also think that this book won’t do the job with teenagers who still don’t have the arsenal of mental models, for them this book is full of unclear shortcuts.
The book is based on the materials of a highly praised blog fs.blog and is a good example how some stuff can work well as a blog post but feel bad as a book.
The bottom line: 2/5 Skip it.
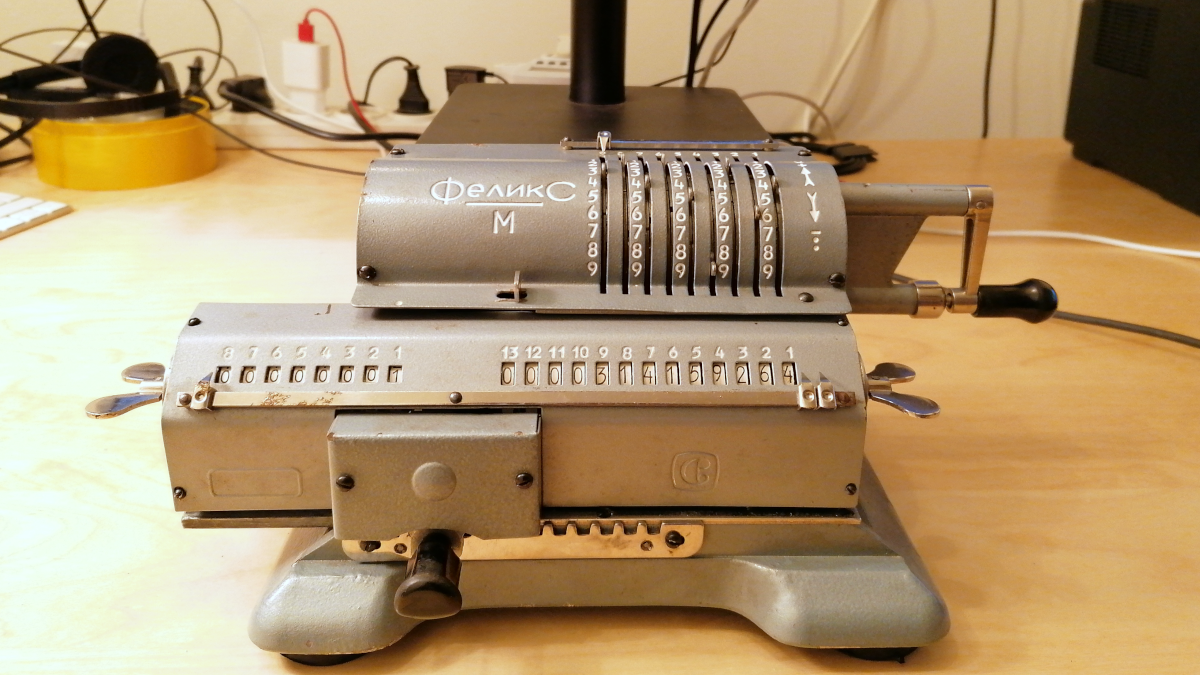
Which data scientists can refuse more computing power? None. My collection of computing devices has a new addition a Soviet arithmometer Felix M.
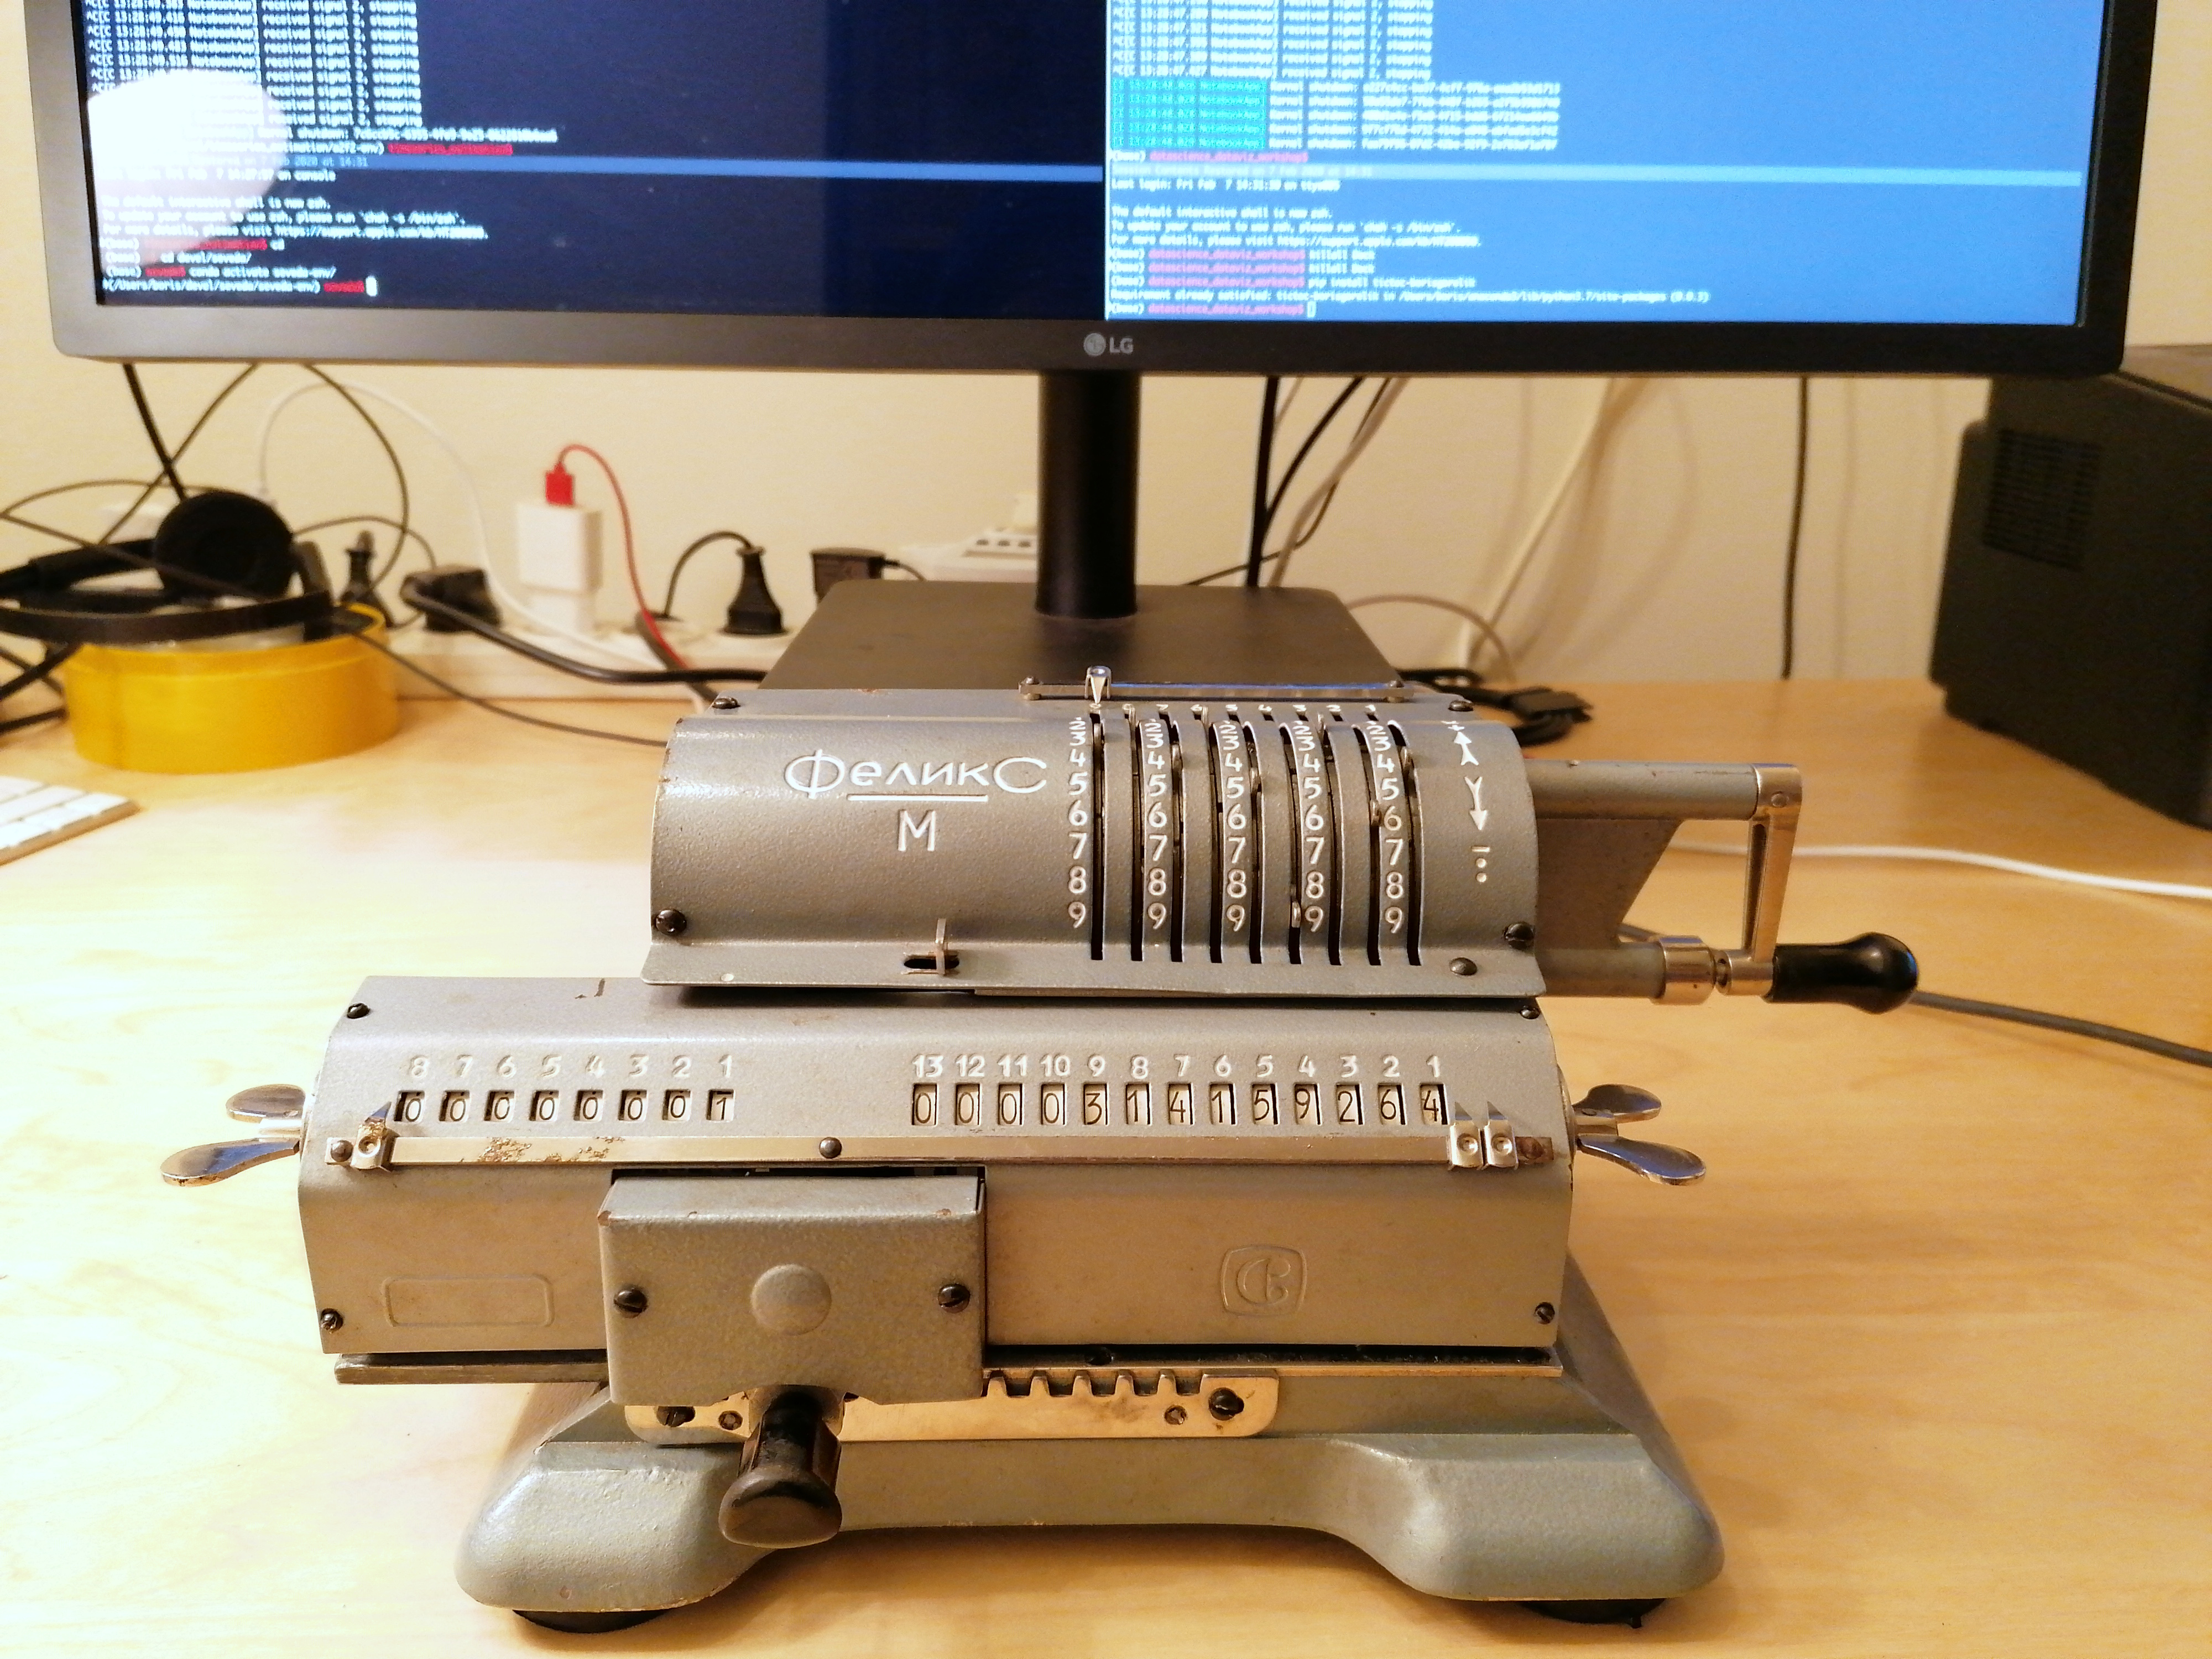
Many years ago, I needed a way to measure execution times. I didn’t like the existing solutions so I wrote my own class. As time passed by, I added small changes and improvements, and recently, I decided to publish the code on GitHub, first as a gist, and now as a full-featured Github repository, and a pip package.
TicToc provides a simple mechanism to measure the wall time (a stopwatch) with reasonable accuracy.
Crete an object. Run tic() to start the timer, toc() to stop it. Repeated tic-toc’s will accumulate time. The tic-toc pair is useful in interactive environments such as the shell or a notebook. Whenever toc is called, a useful message is automatically printed to stdout. For non-interactive purposes, use start and stop, as they are less verbose.
Following is an example of how to use TicToc:
def leibniz_pi(n):
    ret = 0
    for i in range(n * 1000000):
        ret += ((4.0 * (-1) ** i) / (2 * i + 1))
    return ret

tt_overall = TicToc('overall')  # started  by default
tt_cumulative = TicToc('cumulative', start=False)
for iteration in range(1, 4):
    tt_cumulative.start()
    tt_current = TicToc('current')
    pi = leibniz_pi(iteration)
    tt_current.stop()
    tt_cumulative.stop()
    time.sleep(0.01)  # this inteval will not be accounted for by `tt_cumulative`
    print(
        f'Iteration {iteration}: pi={pi:.9}. '
        f'The computation took {tt_current.running_time():.2f} seconds. '
        f'Running time is {tt_overall.running_time():.2} seconds'
    )
tt_overall.stop()
print(tt_overall)
print(tt_cumulative)
TicToc objects are created in a “running” state, i.e you don’t have to start them using tic. To change this default behaviour, use
tt = TicToc(start=False)
# do some stuff
# when ready
tt.tic()
Install the package using pip
pip install tictoc-borisgorelik
Any dispute that is for the sake of Heaven is destined to endure; one that is not for the sake of Heaven is not destined to endure
Chapters of the Fathers 5:27
One day, I had an intense argument with a colleague at my previous place of work, Automattic. Since most of the communication in Automattic happens in internal blogs that are visible to the entire company, this was a public dispute. In a matter of a couple of hours, some people contacted me privately on Slack. They told me that the message exchange sounded aggressive, both from my side and from the side of my counterpart. I didn’t feel that way. In this post, I want to explain why it is OK to have a loud argument with your co-workers.
I’m a data scientist and algorithm developer. I like doing data science and developing algorithms. Sometimes, to be better at my job, I need to show my work to my colleagues. In a “regular” company, I would ask my colleagues to step into my office and play with my models. Automattic isn’t a “regular” company. At Automattic, people from more than sixty countries from in every possible time zone. So, I wanted to start a server that will be visible by everyone in the company (and only by them), that will have access to the relevant data, and that will be able to run any software I install on it.
X is a system administrator. He likes administrating the systems that serve more than 2000,000,000 unique visitors in the US alone. To be good at his job, X needs to make sure no bad things happen to the systems. That’s why when X saw my request for the new setup (made on a company-visible blog page), his response was, more or less, “Please tell me why do you think you need this, and why can’t you manage with what you already have.”
Frankly, I was furious. Usually, they tell you to count to ten before answering to someone who made you angry. Instead, I went to my mother-in-law’s birthday party, and then I wrote an answer (again, in a company-visible blog). The answer was, more or less, “because I know what I’m doing.” For which, X replied, more or less, “I know what I do too.”
At this point, I started realizing that X is not expected to jeopardize his professional reputation for the sake of my professional aspirations. It was true that I wanted to test a new algorithm that will bring a lot of value to the company for which I work. It is also true that X doesn’t resent to comply with every developers’ request out of caprice. His job is to keep the entire system working. Coincidentally, X contacted me over Slack, so I took the opportunity to apologize for something that sounded as aggression from my side. I was pleased to hear that X didn’t notice any hostility, so we were good.
I don’t know whether it was possible to achieve the same or a better result without the loud argument. I admit: I was angry when I wrote some of the things that I wrote. However, I wasn’t mad at X as a person. I was angry because I thought I knew what was best for the company, and someone interfered with my plans.
I assume that X was angry when he wrote some of the things he wrote. I also believe that he wasn’t angry at me as a person but because he knew what was best for the company, and someone tried to interfere with his plans.
I’m sure though that it was this argument that enabled us to define the main “pain” points for both sides of the dispute. As long as the dispute was about ideas, not personas, and as long as the dispute’s goal was for the sake of the common good, it was worth it. To my current and future colleagues: if you hear me arguing loudly, please know that this is a “dispute that is for the sake of Heaven [that] is destined to endure.”
Featured image: Source: http://mimiandeunice.com/; Bees image: Photo by Flickr user silangel, modified. Under the CC-BY-NC license.
I don’t have much hair on my head, but recently, I encountered a funny peculiarity in Python due to which I have been pulling my hair for a couple of hours. In retrospect, this feature makes a lot of sense. In retrospect.
First, let’s start with the mental model that I had in my head: inheritance.
Let’s say you have a base class that defines a function f
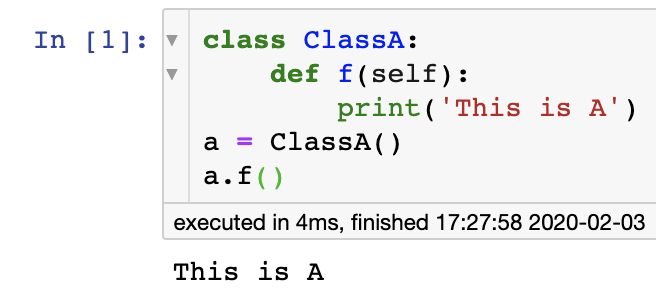
Now, you inherit from that class and rewrite f
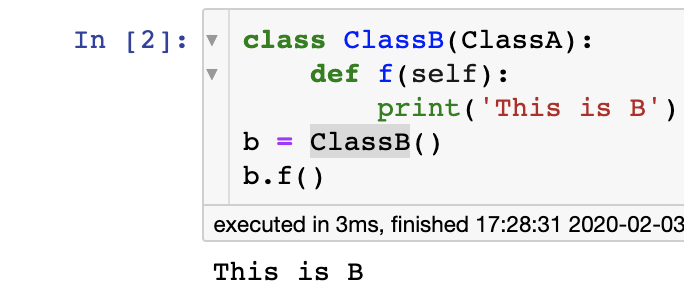
What happens? The fact that you defined f in ClassB means that, to a rough approximation, the old definition of f from ClassA does not exist in all the ClassB objects.
Now, let’s go to decorators.
@dataclass_json
@dataclass
class Message2:
    message: str
    weight: int
    def to_dict(self, encode_json=False):
        print('Custom to_dict')
        ret = {'MESSAGE': self.message, 'WEIGHT': self.weight}
        return ret
m2 = Message2('m2', 2)
What happened here? I used a decorator dataclass_json that, among other things, provides a to_dict function to Python’s data classes. I created a class Message2, but I needed s custom to_dict definition. So, naturally, I defined a new version of to_dict only to discover several hours later that the new to_dict doesn’t exist.
Do you get the point already? In inheritence, the custom implementations are added ON TOP of the base class. However, when you apply a decorator to a class, your class’s custom code is BELOW the one provided by the decorator. Therefore, you don’t override the decorating code but rather “underride” it (i.e., give it something it can replace).
As I said, it makes perfect sense, but still, I missed it. I don’t know whether I would have managed to find the solution without Stackoverflow.
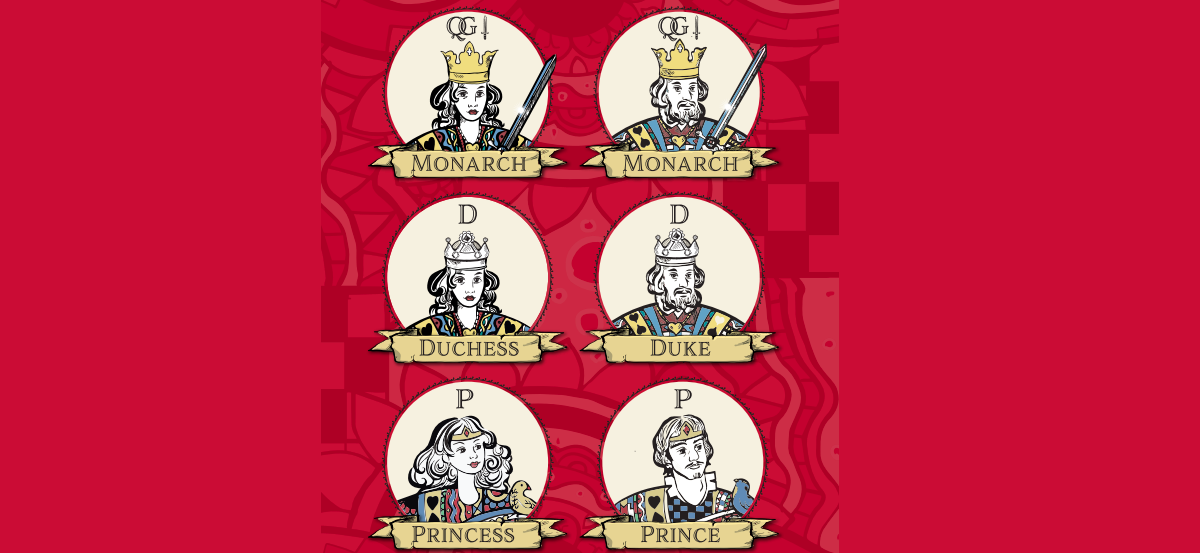
Queeng is an ambitious project to change the way we play cards.
Today, I read a post about Ziph’s law and Alzheimer’s disease. I liked the post very much and decided to press the “like” button only to discover that I already “liked” this post more than two years ago.
Indeed this is an interesting post.
You know that I’m a data science consultant now, don’t you? You know that AnnMaria De Mars, Ph.D. (the statistician, game developer, the world Judo champion) is one of my favorite bloggers, and her blog is the second blog I started to follow don’t you?
A couple of months ago, AnnMaria wrote an extensive post about 30 things she learned in 30 years as a statistical consultant. One week ago, she wrote another great piece of advice.
I’ll be speaking about being a statistical consultant at SAS Global Forum in D.C. in March/ April. While I will be talking a little bit about factor analysis, repeated measures ANOVA and logistic regression, that is the end of my talk. The first things a statistical consultant should know don’t have much to do with…
The first things a statistical consultant needs to know — AnnMaria’s Blog